Translate a PDF into German — every field, table and checkbox still where it was.
- Script
- Latin
- Bundled font file
- NotoSans-Regular.ttf
- Language tag
- de
A real document, before and after
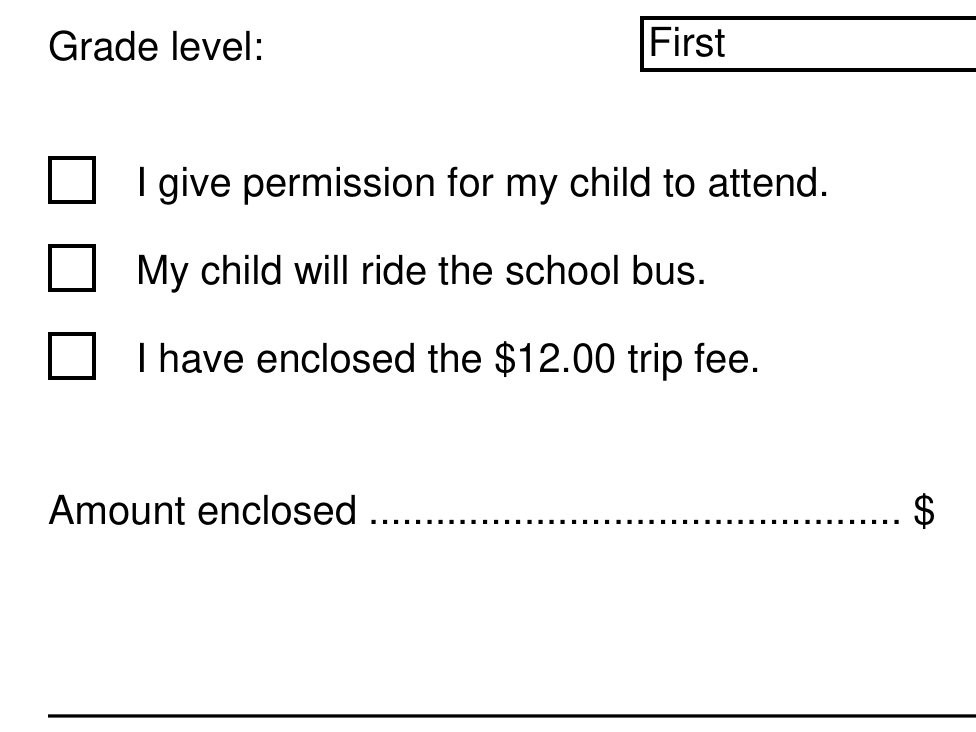
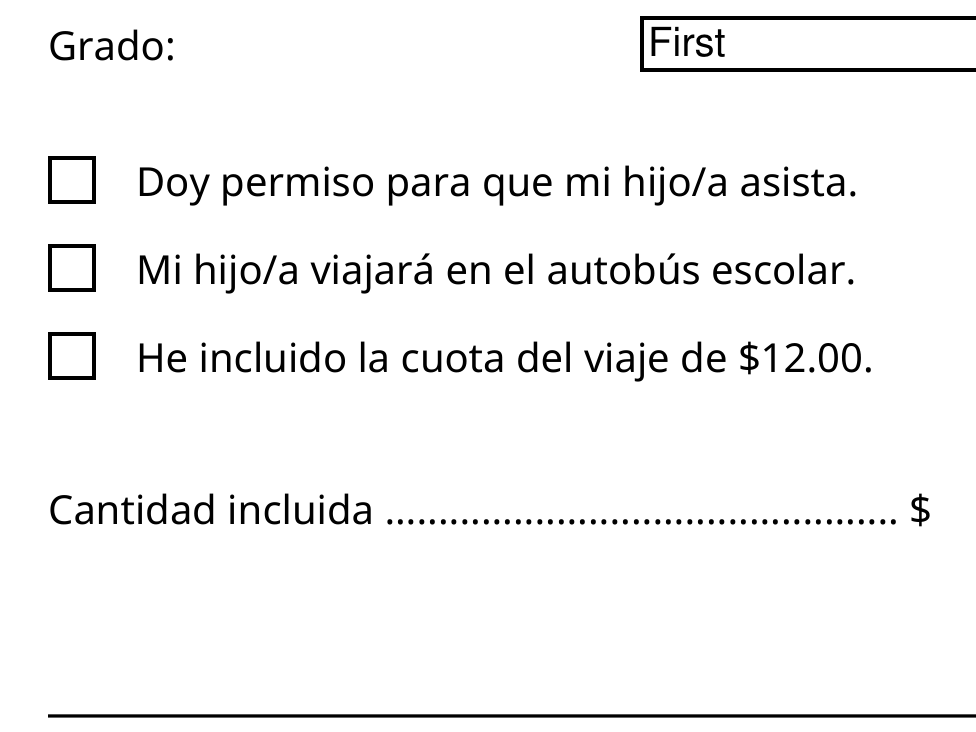
A public-domain form put through this engine. This sample was translated into Spanish; the rules on this page are the same for any language we draw.
Produced by this engine on September 13, 2026 from a public-domain form. No part of this image was edited by hand.
This is a working copy to help you understand the document — not a certified translation.
What changes when you translate into German
Every block, every color and every margin is kept — each block goes back in its own place, and nothing around it moves.
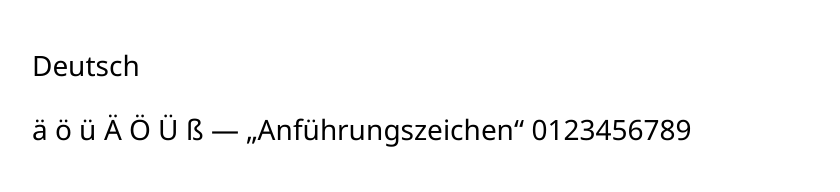
- German draws from the bundled Latin faces, and its probe line covers the umlauts over the letters a, o and u in both cases plus the sharp-s ligature and German-style low-high quotation marks. Every one of those measures a clean, fully covered set against the committed face. Every German noun is capitalized mid-sentence, not only at the start of one, so the probe also confirms the umlauted capital letters render as cleanly as their lowercase forms.
- Bold and italic German text is preserved as bold and italic: the engine resolves a separate face file for each of the four style combinations from the run's own flags, so an emphasized compound noun never returns in the plain weight.
- German compounds are famously long, and the engine never splits or hyphenates a token to make it fit — a single unbroken word like Rechtsschutzversicherung, the everyday German term for legal-expenses insurance, is exactly the case its fit ladder is tested against: it wraps at the next available space before or after the whole word, never partway through it. Translated German prose typically runs longer than its English source for the same reason that one compound word does: German welds several separate English words into a single long compound noun, so the same sentence often needs noticeably more letters even where it uses fewer separate words. When a full line runs long rather than one unbroken word, the same ladder applies: wrap at the next space, step down but never past 75% of the original size, grow into any empty space below, then harmonise the type size across the units sharing a source style, so no block sits at an odd size beside its neighbours; a line that still does not fit keeps its original wording untouched and the page is flagged.
- Not yet. Scanned pages have no text layer, so there's nothing on them to translate. Remove them before you get a price; the translated PDF contains the pages you kept. If every page looks scanned, there's nothing to translate and nothing to pay. OCR is on the roadmap.
- If a German document carries a character the bundled face cannot draw, the engine replaces it with a placeholder glyph and records that block as glyph_unsupported in the report, rather than hyphenating around it or dropping the character.
Any language we translate into. The bundled fonts draw Latin, Cyrillic, Han (Simplified) and Japanese (kanji, hiragana and katakana). Scripts we do not yet carry a font for — Arabic, Hebrew and others — are replaced with a placeholder and the block is flagged in the report, never silently dropped.